The median vulnerability fix in our study costs about $2,500 in engineering time. The average is about $3,700, because a small number of fixes cost far more. And 82% of Critical and High vulnerabilities fall into the Low or Medium effort bands, which the severity label cannot tell you in advance.
Bruce Fram, Founder and CEO, AppSecAI — November 2026
Those numbers come from a study we presented at OWASP: 15,236 published vulnerabilities across 223 open-source projects, with engineering effort estimated from the patch for 11,652 fixes. They are estimates, and they cover coding and testing the fix, not triage or deployment. The correlation between severity and fix effort is a weak 0.11 (1% correlation between severity and cost).
Application security has been on a four-ERA Taylor Swift tour. Discovery found the bugs. Scoring ranked them. AI automation found a lot more of them. Remediation, where somebody changes the code and ships it, is last on the tour. Just like in real life. The industry keeps buying tickets to Discovery and engineering keeps getting the bill, so we wanted to see the bill.
The Short Version
- The median fix takes 16 engineering hours, about $2,500, for coding and testing alone. The average is about $3,700.
- Severity does not size the work. The correlation between severity and fix effort is a weak 0.11 (a little over 1%). Think of it as how loud a car alarm is and whether the car is being stolen.
- 82% of Critical and High fixes are Low or Medium effort.
- 14% of fixes consume 33% of the engineering work.
- Anthropic-credited fixes look like everything else: 85% Low or Medium effort, against 86% for the rest.
- Where to start: the severe findings that are Low effort. They are 41% of Critical and High findings and 18% of the work on severe findings. Explore the data at appsecai.io/fixcost.
How Much Does It Cost to Fix a Vulnerability?
The median fix in our corpus takes 16 engineering hours. The average is 23.7 hours, pulled up by a small number of very expensive fixes.
Turning hours into dollars takes one assumption, and it is yours to change. We use about $150 an hour, which is a $250,000 fully loaded engineer. At that rate the median fix costs about $2,500 and the average about $3,700.
We scored each public fix on three things: how much code changed, how hard the fix was to reason out, and how hard it was to validate. Those scores sort every fix into one of four effort bands, from Low to Extra High. Severity is not an input. The full method is near the end of this post. Here is what each band costs:
| Effort band | Median hours | Cost at $100/hr | At $150/hr | At $200/hr |
|---|---|---|---|---|
| Low | 12 | $1,200 | $1,875 | $2,400 |
| Medium | 24 | $2,400 | $3,750 | $4,800 |
| High | 56 | $5,600 | $8,750 | $11,200 |
| Extra High | 120 | $12,000 | $18,750 | $24,000 |
What the estimate includes and excludes
Fixing a vulnerability takes eleven steps: scan the application, triage and prioritize, assign to a developer, track it through the workflow, code the fix, develop a test case, unit test, rework and retest, move the fix into integration test, deploy, and close the ticket.
Our estimate covers steps five through nine: coding the fix, developing the test case, unit testing, rework, and integration.
Scanning, triage, assignment and tracking come before that, and deployment and closeout come after. None of them is in the estimate, and neither is coordination, disclosure, or the loss you prevented by fixing the thing.
So $2,500 is the median for the middle of the process. The whole bill is bigger. On this blog we have put the full eleven-step cost at $5,000 to $20,000 per fix. This study covers the part nobody had put numbers on, and you can run your own numbers in our ROI calculator.
What 1,000 fixes could cost
As an illustration you can take to a CFO: if a backlog had the same mix as our corpus, 1,000 fixes would come to about 2,960 engineer-days. That is roughly 15 engineer-years, or $3.7 million at the study rate.
That total uses the $3,700 average. The $2,500 median describes a typical fix, but the average is the number to multiply by because it includes the expensive tail.
About 490 of those fixes are Low effort and take under 700 days combined, while about 144 are High or Extra High and take about 970.
Before you apply this to your own numbers, remember that 1,000 scanner findings are not 1,000 fixes. Some are duplicates or false positives, and one upgrade or one code change often closes several findings. Your mix will differ, which is the reason to measure it.
Finding One: Severity Does Not Size the Work
The correlation between severity and effort is a weak 0.11.
For anyone who has not thought about Spearman's rho since a statistics class: it measures how well one ranking predicts another, where 1.0 is perfect and 0 is none. At 0.11 the relationship is weak. Rank every fix by severity and you learn almost nothing about where it ranks on effort. The correlation between the raw CVSS score and modeled days is 0.10.
What that looks like in a backlog:
- 82% of Critical and High vulnerabilities are Low or Medium effort to fix. That is 4,405 out of 5,362.
- 13% of Low-severity vulnerabilities are High or Extra High effort. That is 104 of 822. The easiest-looking items in a backlog include some of the hardest work.
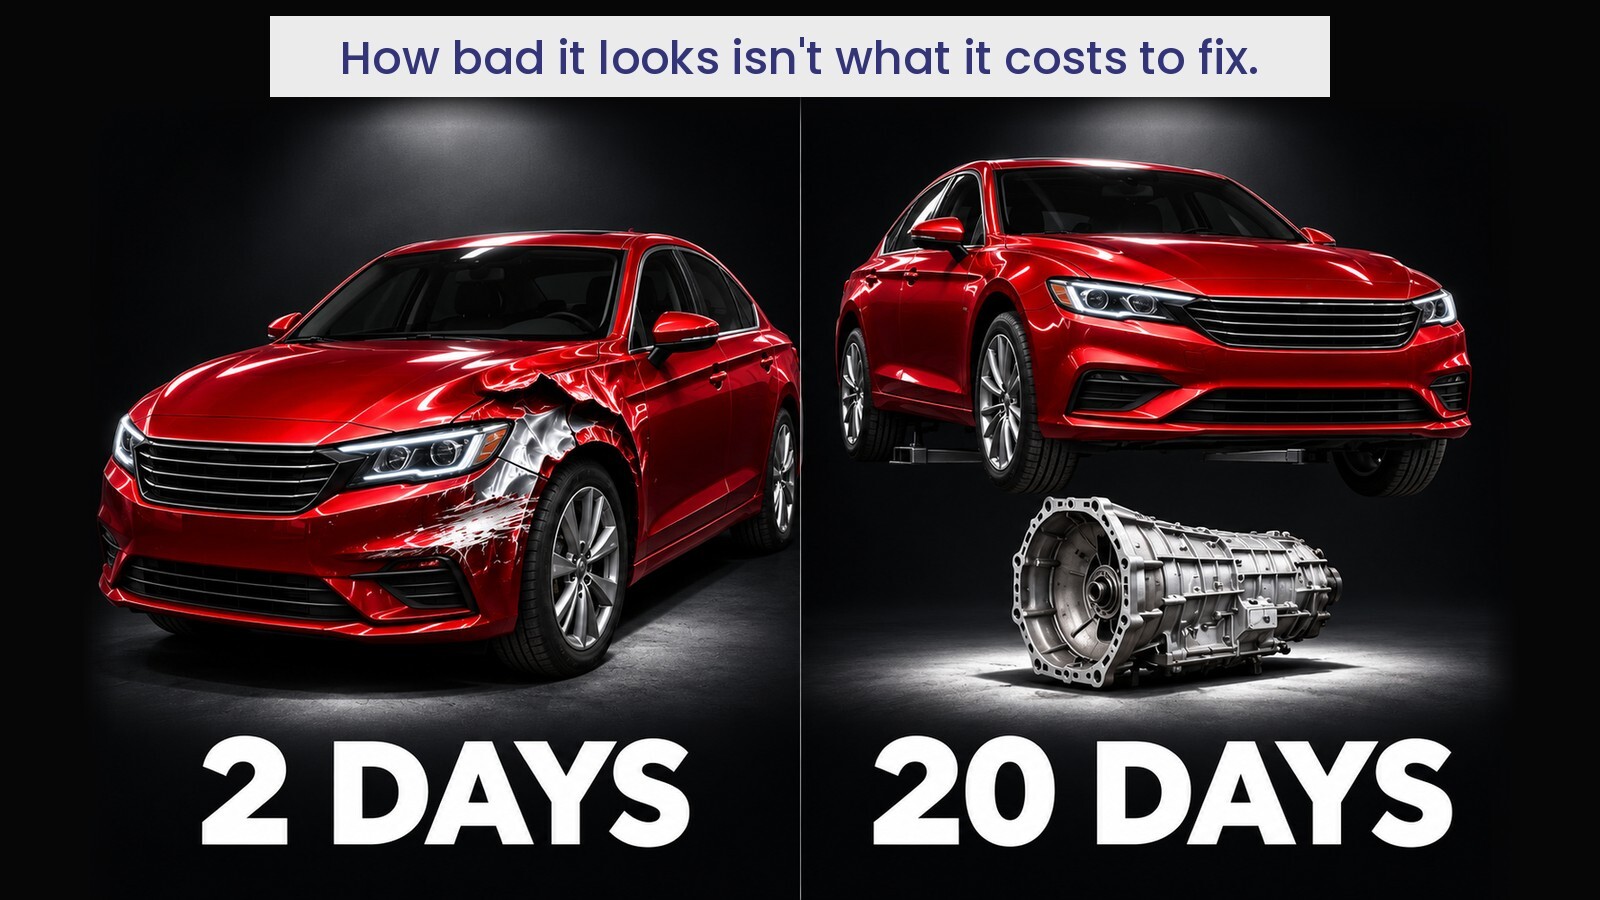
Two patches, nearly the same size
Apache Tomcat CVE-2019-0232 is rated High, CVSS 8.1. The fix is 54 lines of implementation code across three files. It needed modest reasoning and modest validation. Modeled effort: two engineer-days.
Firefox CVE-2024-9400 is rated Low. The fix is 55 lines. It scored the maximum on both reasoning and validation. Modeled effort: twenty engineer-days.
One line of code apart, ten times the work, and the severity labels point the wrong way.
Raw patch size misleads too. Node.js CVE-2025-55130 shows 112 changed lines across 6 files. Strip out the tests and fixtures and 52 lines across 2 files remain. That lands in Medium: about five engineer-days, most of it reasoning and validation.
What this changes
Most remediation SLAs are keyed to severity alone. A policy that gives every Critical the same deadline assumes every Critical is the same amount of work, and it is not. Make the urgency decision and the work estimate separately. The severity label answers "how bad would this be?" It was never designed to answer "what will this take?"
Finding Two: A Small Tail Eats a Third of the Budget
Here is the distribution across all 11,652 estimated fixes:
| Effort band | Fixes | Share of fixes | Engineer-days | Share of work |
|---|---|---|---|---|
| Low | 5,735 | 49% | 7,994 | 23% |
| Medium | 4,235 | 36% | 15,180 | 44% |
| High | 1,538 | 13% | 9,099 | 26% |
| Extra High | 144 | 1% | 2,203 | 6% |
High and Extra High together are 14% of the fixes and 33% of the work. Extra High alone is 1% of the fixes and 6% of the work.
The tail tracks vulnerability class. A cross-site scripting fix runs a median of a day and a half. A race condition runs ten days. A JIT miscompilation runs fifteen, and not one of the 33 in our corpus was Low or Medium effort. One caveat: class feeds the model's default scores for reasoning and validation, so these profiles describe modeled estimates. Use them to decide which questions to ask. They do not prove that class predicts hours.
That asymmetry is why a count of open findings says little about the capacity you need. At those medians, 500 cross-site scripting fixes are about 750 engineer-days. 500 race conditions are about 5,000. Same count on the dashboard, nearly seven times the work.
What this changes
Report the backlog in engineer-days, because a finding count hides the tail. Give the difficult tail what it needs: an owner, a reviewer, engineering time, and a decision about containing the exposure while the fix is built.
Finding Three: The Component Name Is Lying to You
Where a fix lands in the codebase changes the work: engine-layer fixes are High or Extra High effort 19% of the time, front-end UI fixes 3%. The catch is that the component name will not tell you the layer. Flowise, the AI orchestration tool, has a component called "Frontend Builder Web UI & Standard CRUD APIs." Of the 14 vulnerabilities in it, 8 were business-logic fixes, 5 were API and controller fixes, 1 was unclassified, and none touched front-end UI.
Route and estimate by the files a fix touches and ignore the component label on the ticket. That is also how you pick the right reviewer the first time.
More Findings Are Coming. The Fixes Look the Same.
Finding vulnerabilities is no longer the hard part. Anthropic's coordinated disclosure program showed 29,439 candidate findings as of October 2, with 6,157 reported to maintainers and 516 patched upstream. OpenAI and Trail of Bits' Patch the Planet showed 2,055 issues and 472 accepted upstream as of October 30, 48% of them in one project, scapy. These are different programs at different stages, and neither figure is a score. Chris Hughes at Resilient Cyber framed the constraint: discovery capacity and remediation capacity are separate problems.
Our corpus has 176 estimated fixes that credit Anthropic or Claude, across 27 projects, identified with Patrick Garrity's Anthropic Credited CVEs tracker at VulnCheck. 85% are Low or Medium effort, against 86% for the 11,442 fixes without that credit.
That comparison has limits. Credit does not identify a model or prove the discovery was autonomous, and a similar share of Low and Medium fixes does not prove equal cost. Project mix matters too: within Firefox, the credited fixes are 48% High or Extra High effort, against 22% for the uncredited.
So in this corpus, Anthropic-credited fixes look like everything else, and more of them are arriving. Garrity's list shows about 50 a month since August, up from 17 to 37 a month from March through July.
"That's Open Source. My Code Is Different."
This is the first objection we hear, and it is partly right.
The study models what it took to create each fix upstream. That makes it a proxy for fixing similar vulnerabilities in code you own: the same classes of bug, in the kinds of applications enterprises build and run: healthcare systems, business apps, collaboration tools, identity platforms.
It does not tell you what a third-party vulnerability costs you. When GitLab or Tomcat ships a fix, your work is upgrading, testing and deploying the fixed version. That is a different workload, and it is outside this estimate.
For first-party code, your review culture, release process and test coverage will change the hours. That is why the method is built to be calibrated. We are testing it against internal repositories where real hours were tracked, and you can run it on yours.
What to Do With This on Monday
Stop sorting the backlog on one axis. Severity tells you whether something matters. Effort tells you what it costs. You need both, and in our data they are only weakly related.
Plot the corpus on severity against effort and it falls out like this:
| Low / Medium effort | High / Extra High effort | |
|---|---|---|
| Critical / High severity | Automate. 38% of fixes, 32% of the work. Start here, and verify the deployed fix. | Work with engineering. 8% of fixes, 19% of the work. Assign capacity promptly. |
| Moderate / Low severity | Batch. 47% of fixes, 35% of the work. Group suitable work where it removes real exposure. | Defer. 6% of fixes, 14% of the work. Reassess as exposure changes. |
Start with the top-left box. 38% of the corpus is both severe and Low or Medium effort. Narrow it to the Low-effort fixes alone and the trade gets better: 41% of all Critical and High findings for 18% of the work on severe findings. That compares finding counts with effort. It does not mean 41% of the risk is gone, and local exposure still comes first.
That box is also where automation fits best, because the changes are bounded and the results can be tested. It is what we built Expert Fix Automation (EFA) for. EFA generates the fix as a pull request in your existing workflow, and a human reviews it, in 8.2 minutes on average. The hard 8% in the top-right box still needs your best engineers. The point is to stop spending them on the 38%.
Do not turn this into a formula. Urgency is more than a CVSS column: it needs evidence about what you deploy, what is reachable, and what is being exploited. Effort helps you sequence work of comparable urgency. It never overrides active exploitation. Do not build CVSS divided by engineer-days into a dashboard and call it strategy.
Four steps:
- Confirm local exposure. Is the vulnerable code deployed here, and is it reachable?
- Find the fix that closes it. A maintained upgrade, a bounded patch, or removing functionality you do not use.
- Verify tests, release safety and deployment. A merged fix that never deploys removes no risk.
- Record what it took. Then compare it to the model, and calibrate.
The Number Everyone Quotes Is the Wrong Number
Ask how long it takes to fix a vulnerability and you get Veracode's answer: a median of 243 days. Veracode has great data and this number is quoted everywhere (for good reason).
The number is real, but it measures elapsed time. Most of those 243 days are queue time. The finding sat in a backlog waiting for a sprint and an owner. Very little of it is someone writing code.
Our data puts a number on the other side. The median fix in our corpus takes 16 engineering hours. That is two days of work inside eight months of waiting. The two figures come from different datasets, so treat the comparison as directional, but the direction is hard to miss.
A CISO planning headcount does not need to know how long a ticket sits. They need to know how many engineer-days the backlog represents. A VP of Engineering being asked to absorb 2,000 findings needs to know whether that is two sprints or two years. Nobody could answer that, because effort data lives inside private repositories, attached to work that few teams track that precisely.
Open source does publish it, in the form of the patch. Every public fix shows what the fix required: the files it touched and the tests it needed.
So we stopped asking engineers how long things took and started reading what they shipped.
How We Built the Estimate
The corpus covers 223 projects across 15 programming languages: Firefox, GitLab, Keycloak, Apache Tomcat, PostgreSQL, Django, curl, Jenkins, Mattermost, Nextcloud, SuiteCRM, OpenEMR, Open WebUI, n8n. This is software enterprises run.
For each vulnerability we matched the finding to its public fix, then scored the patch on three dimensions, each from 1 to 5:
- Implementation footprint. How much code changed. Tests, documentation and generated content are stripped out first, which cut the Node.js patch above from 112 lines to 52.
- Reasoning complexity. How hard it is to work out what the correct fix is.
- Validation difficulty. What it takes to prove the fix works and did not break something else.
The three scores combine into an effort band: Low (3 to 7), Medium (8 to 9), High (10 to 11), Extra High (12 to 15). Each band maps to a nonlinear curve of engineer-days. Fixes that share a patch are counted once.
Keep two things in mind when you read the findings.
Severity is not an input. Neither CVSS nor the vendor's label nor exploitability touches the effort score, which is why the severity result is a finding and not a circular argument.
These are modeled estimates. We read patch evidence, and nobody at Mozilla logged hours for us. The method has been reviewed and refined over most of a year, and it is still a model.
What This Study Cannot Tell You
Research that only lists its strengths is marketing.
The estimates are modeled from patch evidence. Calibrate against your own team before you put them in a commitment.
The records are not independent. Some fixes resolve several vulnerabilities at once. We allocate that work once, which means the records are not 11,652 separate patches.
You might suspect that a handful of huge projects drive everything, so we tested it. Remove the three largest contributors of effort (Firefox, OpenClaw and GitLab) and 9,793 fixes remain. The difficult tail is still 14% of fixes and carries 30% of the work, down from 33%. Severe fixes that are Low or Medium effort go from 82% to 83%.
The pattern does not depend on three projects.
From our work, the overall trends have held since we did our first project. Look at these in aggregate. Do not focus on any individual fix, it might be wrong.
Welcome to the Remediation Era
Discovery, Scoring and AI automation have all had their tour. This is the era where somebody changes the code, proves it works, and ships it, and it is the only era that removes risk.
The good news in this data is that most of that work is not hard. 82% of severe findings are Low or Medium effort. What has been missing is a way to tell which 82% before you commit the sprint.
Start with the data. Every number in this post, filterable by language, class, layer, difficulty and project, with the assumptions set to your own rates: appsecai.io/fixcost
Two more things you can do:
- Run it on your own code. If you want to know how well the method predicts your team's work, get in touch.
- Validate a fix. OWASP OASIS pairs AI-generated candidate fixes with human reviewers. Pick a codebase you know, check one candidate, and record what the review took. It is the capacity problem in this post at small scale.
The Hidden Effort Curve of Remediation was presented by Bruce Fram and Michael Cartsonis at OWASP. Data: AppSecAI Open Source Remediation Dataset, October 31, 2026. Engineer-days and costs are modeled from patch evidence. Anthropic credit data from Patrick Garrity's Anthropic Credited CVEs repository at VulnCheck. Program figures from Anthropic's coordinated disclosure dashboard and Trail of Bits' Patch the Planet.
AppSecAI automates vulnerability remediation (triage and fix) with 97% triage accuracy and an average human review time of 8.2 minutes per fix. Pay per fix, not per scan.